We've been using Claude Opus 4.7 since it launched last week.
The practical experience is matching the benchmark data Anthropic published.
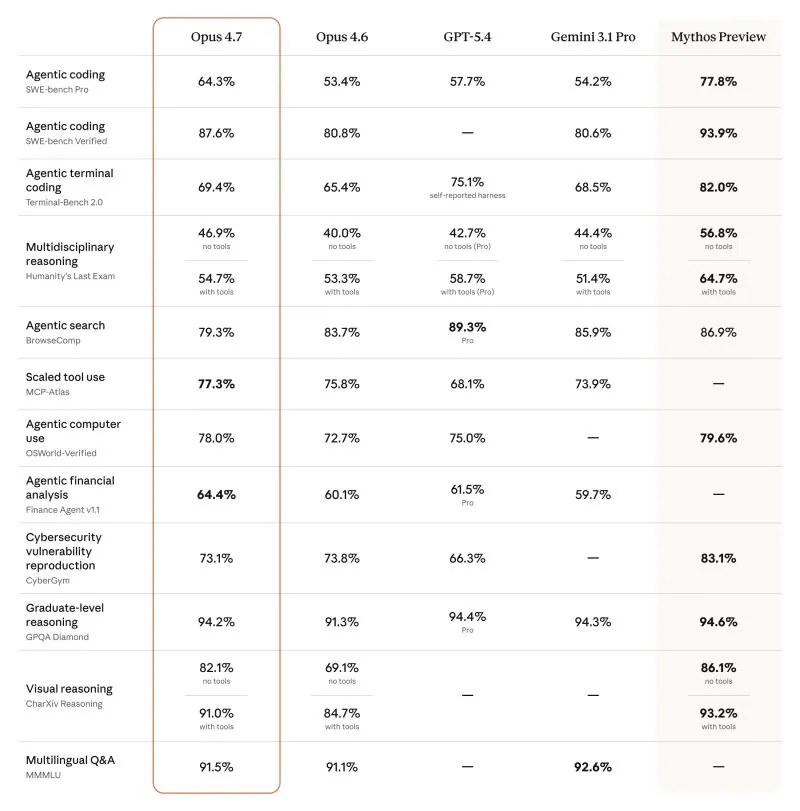
- Coding is a genuine leap forward compared to 4.6 and other models.
- Multi-step reasoning is working noticeably better.
- Visual capabilities are a step up.
If Opus 4.7 is this good, I'm excited to see what Mythos brings.
Benchmarks data from Anthropic below.
First published on LinkedIn.